multi-agents
Multi-agent teams for real work: measured, not assumed.



Docs · Quickstart · Teams · Benchmark · Roadmap
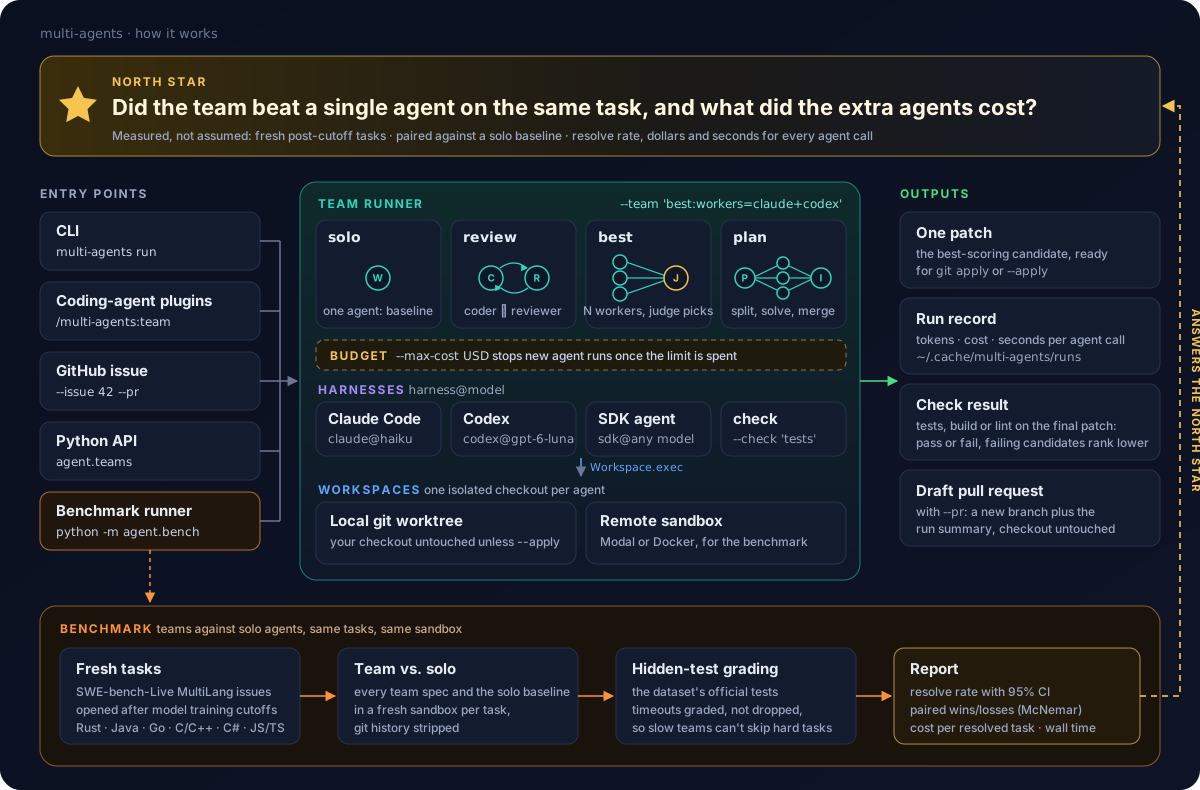
North star: most agent orchestrators skip one question, and the benchmark here answers it: did the team beat a single agent on the same task, and what did the extra agents cost?
Run a team of coding agents on a task in your repository: a single agent, a coder ⇄ reviewer
loop, or several agents with a judge. Workers are the coding CLIs you already use (Claude Code,
Codex) or a built-in agent that can use any model through the OpenAI Agents SDK. Each worker
gets its own git worktree. You get one patch back, plus an itemized record of every agent call:
tokens, cost and seconds. Your working tree is untouched unless you pass --apply.
Why measure
The evidence on teams of coding agents points both ways:
- A 260-configuration study found multi-agent setups 2–15% worse than single agents on SWE-bench Verified (Towards a Science of Scaling Agent Systems).
- A team with a coordinator, a researcher, an engineer and a reviewer reached 72.2% on SWE-bench Verified, 7.2 points better than mini-SWE-agent but only 0.4 above the strongest single-agent baseline, with different models per role (Agyn). A decentralized pair, a patch editor and a validator with isolated context, gained 3.6 and 8.4 points over mini-SWE-agent (icat-agent).
- The best-known coding benchmark is contaminated: OpenAI stopped reporting SWE-bench Verified in February 2026.
So the answer depends on the topology, the models and the task, and published numbers may be contaminated. This project measures it on tasks created after the models' training cutoffs, with paired comparisons and cost.
Quickstart
Requirements: Python 3.10+, uv, git, and at least one logged-in
coding CLI (claude or codex). CLI harnesses use your existing login; no API keys needed.
The package is multi-agent on PyPI and the command is multi-agents: run it with uvx as below,
or keep it installed with uv tool install multi-agent (or pipx install multi-agent).
uvx --from multi-agent multi-agents run \
  --repo ~/code/myproject \
  --team 'best:workers=claude@haiku+codex@gpt-6-luna' \
  "Make the tests in test_slug.py pass without editing the tests."
Real output from that command on a small repository:
Team: best:workers=claude@haiku+codex@gpt-6-luna,judge=claude@haiku
role   ┃ harness@model           ┃ tokens in/cached/out ┃    cost ┃ secs
━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━╇━━━━━
worker │ claude@claude-haiku-5-5 │       236k/201k/1.5k │ $0.0096 │ 34.8
judge  │ claude@claude-haiku-5-5 │       194k/157k/2.6k │ $0.0102 │ 42.8
worker │ codex@gpt-6-luna        │         107k/94k/667 │ $0.0025 │ 31.6
judge  │ claude@claude-haiku-5-5 │       192k/149k/3.8k │ $0.0119 │ 52.3
Total: 729k/604k/8.5k tokens, cost $0.0342, 85.0s
scores: [8.0, 8.0]
chosen: 1
Files changed: 1
  slug.py  +6 -3
The run prints the exact git apply command for the final patch and saves a JSON record
outside your repository (~/.cache/multi-agents/runs/).
Teams
| Spec | What happens |
|---|---|
solo:worker=H |
One agent works on the task. This is the baseline. |
review:coder=H,reviewer=H[,rounds=N] |
The coder works; the reviewer scores the patch in a separate copy and sends feedback; the coder resumes its session and revises. Returns the best-scoring patch, not the last one. |
best:workers=H+H[+H...][,judge=H] |
Workers run in parallel, each in its own worktree, possibly different CLIs and models. The judge scores each patch and the best one wins. |
plan:planner=H,workers=H[+H...][,integrator=H][,max_tasks=N][,replans=N][,reviewer=H][,rounds=N] |
A planner splits the task into independent subtasks, workers solve them in parallel worktrees, and the patches are merged; an integrator resolves conflicts and gets one fix pass if the check fails. Subtasks whose worker failed or changed nothing go back to the planner (replans, default 1, 0 = never) for new subtasks that rotated workers solve. With reviewer (and rounds, default 3) every subtask is a coder ⇄ reviewer loop in its own worktree and its best patch is merged. |
H is claude, codex or sdk, optionally with @model, for example claude@haiku,
codex@gpt-6-luna or sdk@litellm/openrouter/<model>. check (the --check command) can be the
reviewer or the judge: a test-driven loop with no LLM reviewer. Details:
team runner guide.
From issue to pull request
--check runs your tests (or build, or lint) against the final patch in a separate worktree and
records pass/fail; with an LLM judge, candidates that fail it rank below those that pass. --issue
takes the task from a GitHub issue, and --pr commits the result to a new branch and opens a draft
pull request with the run summary, without touching your checkout.
multi-agents run --repo . --issue 42 --pr \
  --team 'plan:planner=claude@haiku,workers=claude@haiku+codex@gpt-6-luna' \
  --check 'python3 -m unittest -q'
A real plan run on a repository with two unrelated bugs (without --issue/--pr):
role    ┃ harness@model           ┃ tokens in/cached/out ┃    cost ┃ secs
planner │ claude@claude-haiku-5-5 │       187k/150k/2.0k │ $0.0101 │ 16.8
worker  │ claude@claude-haiku-5-5 │        141k/104k/510 │ $0.0088 │  8.7
worker  │ codex@gpt-6-luna        │          55k/37k/349 │ $0.0024 │  9.7
Total: 385k/291k/2.9k tokens, cost $0.0212, 26.8s
subtask 1 [applied]: Fix word_count in textstats.py (claude@haiku)
subtask 2 [applied]: Fix format_cents in money.py (codex@gpt-6-luna)
check: passed (exit 0, 0.0s) python3 -m unittest -q
Issue text is untrusted input to the agents: don't combine --issue on public repositories with
--permissions bypass or the sdk harness.
Use it from your coding agent
This repository is also a plugin marketplace for both coding CLIs, so a running agent can hand a task to a team and then show you the patch. Install it once:
# Claude Code
claude plugin marketplace add BichengWang/multi-agents
claude plugin install multi-agents@multi-agents

# Codex
codex plugin marketplace add BichengWang/multi-agents
codex plugin add multi-agents@multi-agents
Then, inside Claude Code (the optional spec comes first; the default is a cheap coder ⇄ reviewer pair that pairs the other CLI with the one you are in):
/multi-agents:team make the tests pass
/multi-agents:team best:workers=claude@haiku+codex@gpt-6-luna fix the flaky retry in client.py
In Codex, ask for the skill by name, for example Use $multi-agents:multi-agents to make the tests
pass. Either way the agent runs the published CLI, shows you the summary and the patch, and applies
it only after you say so. The skill is in
plugins/multi-agents.
Safety and cost
- Permissions. By default (
--permissions safe) each CLI runs inside its own sandbox: edits and test commands are confined to the worktree.--permissions bypassturns those checks off and is meant for disposable machines and containers only. Thesdkharness has no permission system. - Cost. Costs come from the CLI's own report or from list prices with a cited source. A run that cannot be priced shows as unpriced and makes the total unpriced; nothing is guessed.
- Budget.
--max-cost USDstops new agent runs once that much has been spent; the team then returns the patch it has so far. It is a stop on new work, not a ceiling: runs already in flight finish (parallel workers run side by side), so the total can overshoot by their cost. An unpriced run cannot be counted, so after one the budget refuses further runs. The CLI therefore rejects a team with an unpriced harness before it starts, unless you pass--allow-unpriced, which counts those runs as $0 and leaves their spend outside the limit. The record and summary show the spend and any refused runs.
Benchmark
The benchmark runs team specs against solo agents on GitHub issues opened after the models'
training cutoffs (SWE-bench-Live MultiLang:
Rust, Java, Go, C/C++, C#, JS/TS), each in a fresh sandbox (Modal, or --backend docker on your
own Docker daemon) with git history stripped. Patches are graded with the dataset's official
hidden tests. The report gives resolve rate with 95%
confidence intervals, paired wins and losses against the solo baseline on the same tasks (exact
McNemar test), cost per task and per resolved task, and wall time. Timeouts are graded rather than
dropped, so slow teams cannot shrink the comparison to the easy tasks.
uv sync --locked --extra bench
python -m agent.bench tasks --since 2026-07-01 --limit 5 --seed 7    # no credentials needed
Setup, methodology, cost estimates and limitations: benchmark guide. First results will be published here.
Status
| Area | State |
|---|---|
Team runner (solo, review, best, plan), Claude Code and Codex harnesses |
✅ Working; smoke-tested with real CLIs |
--check, --issue, --pr, plugins for both CLIs |
✅ Working; smoke-tested end to end |
--max-cost run budget; plan re-planning (replans) and per-subtask review (reviewer) |
✅ Working; smoke-tested with real CLIs |
| SDK harness (any model) | 🧪 Implemented and tested offline; not yet run against a live model |
| Benchmark | 🧪 Built and tested offline; local Docker grading and agent workspaces run live, a team solve and the Modal path not yet |
| Results | ⏳ Pending the first pilot run |
Plans are in docs/ROADMAP.md.
Development
uv sync --locked --extra dev
make test     # ruff + offline tests, no API keys needed
make check    # also the GitHub workflow and attribution tests (Node.js 22+)
make docs     # build the docs site with --strict (DOCS=serve to preview it locally)
The Python tests ignore your global and system git configuration (hooks, signing, aliases).
Reusable orchestration patterns (RefineLoop, BestOfN, SequentialWorkflow, Router) are in
agent/workflows.
Pre-pivot experiments are in this repository's history at the
pre-pivot tag.